Shyam's Slide Share Presentations

VIRTUAL LIBRARY "KNOWLEDGE - KORRIDOR"

This article/post is from a third party website. The views expressed are that of the author. We at Capacity Building & Development may not necessarily subscribe to it completely. The relevance & applicability of the content is limited to certain geographic zones.It is not universal.

TO VIEW MORE CONTENT ON THIS SUBJECT AND OTHER TOPICS, Please visit KNOWLEDGE-KORRIDOR our Virtual Library

Showing posts with label Data. Show all posts

Wednesday, June 7, 2017

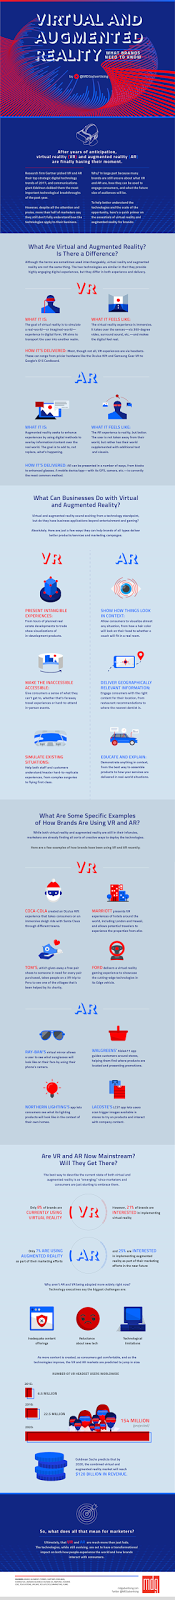
What brands need to know about VR and AR [Infographic] 06-07


Virtual reality (VR) and augmented reality (AR) sound like great novelties on the surface, but what can these technologies do to help your brand? The answer might surprise you. According to this infographic, these experiences can do quite a lot to boost your brand, especially if you are in the business of selling products or experiences.

Product manufacturers and venues are already taking advantage of VR and AR technologies as part of their marketing strategy, and even retail stores are using AR to help customers find what they’re looking for.

This infographic, created by MDG Advertising, outlines some of the reasons brands should start paying attention to this emerging trend.

Virtual reality is finally coming into its own

After years of wait-and-see with VR and AR, tech companies are finally starting to make headway into creating experiences that consumers are responding to. Products like Google’s Daydream and Samsung’s Gear VR have opened the door to enable virtually anyone with a smartphone the chance to experience virtual reality from their smartphones.

Gaming consoles like Sony’s PlayStation even has a VR experience through Sony’s PlayStation VR. Oculus, which is now part of the Facebook family, is driving Facebook’s new Spaces experience where people can meet in a virtual environment.

Linden Lab, the creators of the still-popular virtual world Second Life are hard at work creating a whole new virtual world experience with VR at the forefront.

As for brands, hotels like Marriott are offering potential customers virtual tours of their hotels around the world, enabling them to preview their experience before booking their rooms.


Even product-oriented brands like Coca-Cola are using VR to raise brand awareness through providing fun experiences. Just last year, Coca-Cola showed off packaging that converts into a cardboard VR headset for smartphones.

Augmented reality is helping brands help their customers

Have you ever been lost looking for items in a retail store? We all have, but this is where augmented reality can change the game.

Aisle411 is already being tested with retailers like Walgreens and Toys”R”Us. It creates an augmented reality of sorts that shoppers can use like GPS navigation to get them to the product they’re searching for. A tablet mounted to the shopping cart, or the shopper’s own smartphone, this augmented reality experience makes life easier for the shopper, and that is always best for business.
In addition to announcing better support for Virtual Reality at WWDC this week, Apple unveiled a ARKit, a new development platform for creating augmented reality experiences in iOS. This is a big step as Apple has long been considered the tipping point for augmented reality to really take a leap forward.

The success of Niantic’s Pokemon Go last year introduced a lot of new people to the concept of augmented reality. It remains a fun, and addicting game, but the implications of its success were that brands everywhere became aware that augmented reality is well within reach.


Monday, March 20, 2017

What’s Your Data Worth? 03-20


Many businesses don’t yet know the answer to that question. But going forward, companies will need to develop greater expertise at valuing their data assets.


Image credit : Shyam's Imagination Library


In 2016, Microsoft Corp. acquired the online professional network LinkedIn Corp. for $26.2 billion. Why did Microsoft consider LinkedIn to be so valuable? And how much of the price paid was for LinkedIn’s user data — as opposed to its other assets? Globally, LinkedIn had 433 million registered users and approximately 100 million active users per month prior to the acquisition. Simple arithmetic tells us that Microsoft paid about $260 per monthly active user.

Did Microsoft pay a reasonable price for the LinkedIn user data? Microsoft must have thought so — and LinkedIn agreed. But the deal generated scrutiny from the rating agency Moody’s Investors Service Inc., which conducted a review of Microsoft’s credit rating after the deal was announced. What can be learned from the Microsoft–LinkedIn transaction about the valuation of user data? How can we determine if Microsoft — or any acquirer — paid a reasonable price?

The answers to these questions are not clear. But the subject is growing increasingly relevant as companies collect and analyze ever more data. Indeed, the multibillion-dollar deal between Microsoft and LinkedIn is just one recent example of data valuation coming to the fore. Another example occurred during the Chapter 11 bankruptcy proceedings of Caesars Entertainment Operating Corp.

Inc., a subsidiary of the casino gaming company Caesars Entertainment Corp. One area of conflict was the data in Caesars’ Total Rewards customer loyalty program; some creditors argued that the Total Rewards program data was worth $1 billion, making it, according to a Wall Street Journal article, “the most valuable asset in the bitter bankruptcy feud at Caesars Entertainment Corp.” A 2016 report by a bankruptcy court examiner on the case noted instances where sold-off Caesars properties — having lost access to the customer analytics in the Total Rewards database — suffered a decline in earnings. But the report also observed that it might be difficult to sell the Total Rewards system to incorporate it into another company’s loyalty program. Although the Total Rewards system was Caesars’ most valuable asset, its value to an outside party was an open question.

As these examples illustrate, there is no formula for placing a precise price tag on data. But in both of these cases, there were parties who believed the data to be worth hundreds of millions of dollars.

Exploring Data Valuation

To research data valuation, we conducted interviews and collected secondary data on information activities in 36 companies and nonprofit organizations in North America and Europe. Most had annual revenues greater than $1 billion. They represented a wide range of industry sectors, including retail, health care, entertainment, manufacturing, transportation, and government.

Although our focus was on data value, we found that most of the organizations in our study were focused instead on the challenges of storing, protecting, accessing, and analyzing massive amounts of data — efforts for which the information technology (IT) function is primarily responsible.

While the IT functions were highly effective in storing and protecting data, they alone cannot make the key decisions that transform data into business value. Our study lens, therefore, quickly expanded to include chief financial and marketing officers and, in the case of regulatory compliance, legal officers. Because the majority of the companies in our study did not have formal data valuation practices, we adjusted our methodology to focus on significant business events triggering the need for data valuation, such as mergers and acquisitions, bankruptcy filings, or acquisitions and sales of data assets. Rather than studying data value in the abstract, we looked at events that triggered the need for such valuation and that could be compared across organizations.
We define data value as the composite of three sources of value: (1) the asset, or stock, value; (2) the activity value; and (3) the expected, or future, value.
All the companies we studied were awash in data, and the volume of their stored data was growing on average by 40% per year. We expected this explosion of data would place pressure on management to know which data was most valuable. However, the majority of companies reported they had no formal data valuation policies in place. A few identified classification efforts that included value assessments. These efforts were time-consuming and complex. For example, one large financial group had a team working on a significant data classification effort that included the categories “critical,” “important,” and “other.” Data was categorized as “other” when the value was judged to be context-specific. The team’s goal was to classify hundreds of terabytes of data; after nine months, they had worked through less than 20.

The difficulty that this particular financial group encountered is typical. Valuing data can be complex and highly context-dependent. Value may be based on multiple attributes, including usage type and frequency, content, age, author, history, reputation, creation cost, revenue potential, security requirements, and legal importance. Data value may change over time in response to new priorities, litigation, or regulations. These factors are all relevant and difficult to quantify.

A Framework for Valuing Data

How, then, should companies formalize data valuation practices? Based on our research, we define data value as the composite of three sources of value: (1) the asset, or stock, value; (2) the activity value; and (3) the expected, or future, value. Here’s a breakdown of each value source:

1. Data as Strategic Asset

For most companies, monetizing data assets means looking at the value of customer data. This is not a new concept; the idea of monetizing customer data is as old as grocery store loyalty cards. Customer data can generate monetary value directly (when the data is sold, traded, or acquired) or indirectly (when a new product or service leveraging customer data is created, but the data itself is not sold). Companies can also combine publicly available and proprietary data to create unique data sets for sale or use.

How big is the market opportunity for data monetization? In a word: big. The Strategy& unit of PwC has estimated that, in the financial sector alone, the revenue from commercializing data will grow to $300 billion per year by 2018.

2. The Value of Data in Use

Data use is typically defined by the application — such as a customer relationship management system or general ledger — and frequency of use. The frequency of use is typically defined by the application workload, the transaction rate, and the frequency of data access.

The frequency of data usage brings up an interesting aspect of data value. Conventional, tangible assets generally exhibit decreasing returns to use. That is, they decrease in value the more they are used. But data has the potential — not always, but often — to increase in value the more it is used. That is, data viewed as an asset can exhibit increasing returns to use. For example, Google Inc.’s Waze navigation and traffic application integrates real-time crowdsourced data from drivers, so the Waze mapping data becomes more valuable as more people use it.

The major costs of data are in its capture, storage, and maintenance. The marginal costs of using it can be almost negligible. An additional factor is time of use: The right data at the right time — for example, transaction data collected during the Christmas retail sales season — may be of very high value.

Of course, usage-based definitions of value are two-sided; the value attached to each side of the activity is unlikely to be the same. For example, for a traveler lost in an unfamiliar city, mapping data sent to the traveler’s cellphone may be of very high value for one use, but the traveler may never need that exact data again. On the other hand, the data provider may keep the data for other purposes — and use it over and over again — for a very long time.

3. The Expected Future Value of Data

Although the phrases “digital assets” or “data assets” are commonly used, there is no generally accepted definition of how these assets should be counted on balance sheets. In fact, if data assets are tracked and accounted for at all — a big “if” — they are typically commingled with other intangible assets, such as trademarks, patents, copyrights, and goodwill. There are a number of approaches to valuing intangible assets. For example, intangible assets can be valued on the basis of observable market-based transactions involving similar assets; on the income they produce or cash flow they generate through savings; or on the cost incurred to develop or replace them.
Making implicit data policies explicit, codified, and sharable across the company is a first step in prioritizing data value.

What Can Companies Do?

No matter which path a company chooses to embed data valuation into company-wide strategies, our research uncovered three practical steps that all companies can take.

1. Make valuation policies explicit and sharable across the company. It is critical to develop company-wide policies in this area. For example, is your company creating a data catalog so that all data assets are known? Are you tracking the usage of data assets, much like a company tracks the mileage on the cars or trucks it owns? Making implicit data policies explicit, codified, and sharable across the company is a first step in prioritizing data value.

A few companies in our sample were beginning to manually classify selected data sets by value. In one case, the triggering event was an internal security audit to assess data risk. In another, the triggering event was a desire to assess where in the organization the volume of data was growing rapidly and to examine closely the costs and value of that growth.

The strongest business case we found for data valuation was in the acquisition, sale, or divestiture of business units with significant data assets. We anticipate that in the future, some of the evolving responsibilities of chief data officers may include valuing company data for these purposes. But that role is too new for us to discern any aggregate trends at this time.

2. Build in-house data valuation expertise. Our study found that several companies were exploring ways to monetize data assets for sale or licensing to third parties. However, having data to sell is not the same thing as knowing how to sell it. Several of the companies relied on outside experts, rather than in-house expertise, to value their data. We anticipate this will change. Companies seeking to monetize their data assets will first need to address how to acquire and develop valuation expertise in their own organizations.

3. Decide whether top-down or bottom-up valuation processes are the most effective within the company. In the top-down approach to valuing data, companies identify their critical applications and assign a value to the data used in those applications, whether they are a mainframe transaction system, a customer relationship management system, or a product development system. Key steps include defining the main system linkages — that is, the systems that feed other systems — associating the data accessed by all linked systems, and measuring the data activity within the linked systems. This approach has the benefit of prioritizing where internal partnerships between IT and business units need to be built, if they are not already in place.

A second approach is to define data value heuristically — in effect, working up from a map of data usage across the core data sets in the company. Key steps in this approach include assessing data flows and linkages across data and applications, and producing a detailed analysis of data usage patterns. Companies may already have much of the required information in data storage devices and distributed systems.

Whichever approach is taken, the first step is to identify the business and technology events that trigger the business’s need for valuation. A needs-based approach will help senior management prioritize and drive valuation strategies, moving the company forward in monetizing the current and future value of its digital assets.

Reproduced from MITSLOAN Management Review
Sunday, April 19, 2015

Data science demands elastic infrastructure 04-19

Data science demands elastic infrastructure


Those companies that try to run big data projects in data centers may be setting themselves up for failure. Matt Asay explains. 

As companies struggle to make sense of their increasingly big data, they're laboring to figure out the morass of technologies necessary to become successful. However, many will remain stymied, because they keep trying to fit a necessarily fluid process of asking questions of one's data with outmoded, rigid data infrastructure.
Or as Amazon Web Services (AWS) data science chief Matt Wood tells it, they need the cloud.
While the cloud isn't a panacea, its elasticity may well prove to be the essential ingredient to big data success.

How much cloud do I need?

The problem with trying to run big data projects within a data center revolves around rigidity. As Matt Wood told me in a recent interview, this problem "is not so much about absolute scale of data but rather relative scale of data."
In other words, as a company's data volume takes a step function up or down, enterprise infrastructure can't keep up. In his words, "Customers will tool for the scale they're currently experiencing," which is great... until it's not.
In a separate conversation, he elaborates:
"Those that go out and buy expensive infrastructure find that the problem scope and domain shift really quickly. By the time they get around to answering the original question, the business has moved on. You need an environment that is flexible and allows you to quickly respond to changing big data requirements. Your resource mix is continually evolving--if you buy infrastructure, it's almost immediately irrelevant to your business because it's frozen in time. It's solving a problem you may not have or care about any more."
Success in big data depends upon iteration, upon experimentation as you try to figure out the right questions to ask and the best way to answer them. This is hard when dealing with a calcified infrastructure.

A eulogy for the data center?

Of course, it's not quite so simple as "all cloud, all the time."
Data, it would seem, has to obey fundamental laws of gravity, as Basho CTO Dave McCrory told TechRepublic in an interview:
"Big data workloads will live in large data centers where they are most advantaged. Why will they live in specific places? Because data attracts data.
"If I already have a large quantity of data in a specific cloud, I'm going to be inclined to store additional quantities of large data in the same place. As I do this and add workloads that interact with this data, more data will be created."
Over time, enterprises will look to the public cloud for all the reasons Wood describes, but legacy data is unlikely to make the migration. There's simply no reason to try to house old data in new infrastructure. Not most of the time.
But some companies will find that they're more comfortable with existing data centers and will eschew the cloud. I'm not talking about hide-bound enterprise curmudgeons that shout "Phooey!" every time AWS is mentioned, either. No, sometimes the most data center-centric of companies will be the innovators like Etsy.
As Etsy CTO Kellan Elliott-McCrea informed TechRepublic, once Etsy had "gained confidence" in its ability to manage its Hadoop clusters (and other technology), they brought them in-house, netting a 10X increase in utilization and "very real cost savings."
Nor is Etsy alone. Other new-school web companies like Twitter have opted to run their own data centers, finding that this gives them greater control over their data.

You're no Twitter

As highly as you may estimate your abilities, the reality is that you're probably not an Etsy, Twitter, or Google. As painful as it is to say it, most of us are average. By definition.
This is what Microsoft's great genius was: rather than cater to the Übermensch of IT, Microsoft lowered the bar to becoming productive as a system administrator, developer, etc. In the process, Microsoft banked billions in profits, helping make a good sysadmin better or a decent developer good.
Regardless, all enterprises need to establish infrastructure that helps them to iterate. Some, like Etsy, may have figured out how to do this in their data centers--but for most of us, most of the time, Wood's advice rings true: "You need an environment that is flexible and allows you to quickly respond to changing big data requirements."
In other words, odds are that you're going to need the cloud.

Sunday, February 8, 2015

Your Data Should Be Faster, Not Just Bigger 02-08

Your Data Should Be Faster, Not Just Bigger


It’s universally acknowledged that Big Data is now a fact of life, but while large enterprises have spent heavily on managing largevolumes and disparate varieties of data for analytical purposes, they have devoted far less to managing high velocity data. That’s a problem, because high velocity data provides the basis for real-time interaction and often serves as an early-warning system for potential problems and systemic malfunctions.
wherebigdata (1)
Moreover, data proliferation has been accelerating. EMC recently reported that data volumes can be expected to double every two years, with the greatest growth coming from the vast amounts of new data being produced by intelligent devices and sensors. Oracle president Mark Hurd has predicted that the number of devices connected to the Internet will grow from 9 billion to 50 billion by the end of this decade.
What makes device data, sensor data, and other forms of “fast data” distinctive is that, unlike historical data, it is live, interactive, automatically generated, and often self-correcting. Historical data is used to identify patterns that inform future decision-making, while fast data is designed for real-time decisions and real-time responses. Think of fast data as the continuous processing of events and data in order to gain instantaneous insight and take instantaneous action.
While fast data is not really new, it has been largely restricted to a couple of high-value uses: complex event processing (CEP) activities that operate on event streams, examples of which include algorithmic trading and fraud monitoring in financial services; and event correlation, which includes the systems that monitor and manage complex industrial components such as jet engines.
So, what has changed? First, the explosion of fast data has driven the demand for instant action. Second, innovators in social media and services like Uber have shown that businesses can be differentiated based on their ability to act on data instantly. Uber knows where you are, where you’re going, and how you will pay to get there because it can capture, analyze, and act on data in real time. The availability of lower-cost memory is making fast data accessible for a broader set of applications, including:
  • First responder systems that rely on integrating fast response data collection and analysis
  • Network usage systems that respond instantly based on traffic patterns
  • Customer-experience management systems that analyze vast amount of behavioral data in real time to tailor interactions and support self-service
Organizations that know how to use fast data will be more nimble, adaptive, and competitive. What can companies do differently to prepare for the opportunities created by high-velocity data? Here are a couple of suggestions:
  1. Automate decision-making to increase customer engagement. Monitor customer activities to identify—and respond to—patterns, thresholds, and triggers. One major retailer is seeking to engage with customers in real time while they are online, but is hampered by traditional systems and batch processing environments. They are now creating an environment that marries customer and inventory data with streaming data so they can, for example, report to the customer whether a product is in stock and address any inventory gaps immediately.
  2. Integrate machine-generated data to personalize interactions.EMC projects that soon nearly two-thirds of all data will be generated by machines, not people. That presents a technical challenge: how can companies capture and analyze many flows of data concurrently? The good news is that next-generation data systems that prioritize real-time data are in the early stages of adoption. By integrating new sources of machine-generated data, and combining it with traditional data sources, firms can further personalize their customer interactions. Ericsson, the mobile broadband company, has developed real-time visibility into its system performance, using device and user data as it is generated. This enables Ericsson to identify and improve slow performance as needed and to serve customers with programming tailored to them.
Firms that take these steps now will be well positioned to improve their operations and better serve their customers using high-speed data.

Sunday, December 28, 2014

The New Analytics Imperative 12-29

The New Analytics Imperative

Cisco today announced a data and analytics strategy and a suite of analytics software that will enable customers to translate their data into actionable business insight regardless of where the data resides.
With the number of connected devices projected to grow from 10 billion today to 50 billion by 2020, the flood tide of new data — widely distributed and often unstructured — is disrupting traditional data management and analytics. Traditionally most organizations created data inside their own four walls and saved it in a centralized repository. This made it easy to analyze the data and extract valuable information to make better business decisions.
But the arrival of the Internet of Everything (IoE) — the hyper-connection of people, process, data, and things – is quickly changing all that. The amount of data is huge. It’s coming from widely disparate sources (like mobile devices, sensors, or remote routers), and much of that data is being created at the edge. Organizations can now get data from everywhere — from every device and at any time — to answer questions about their markets and customers that they never could before. But IT managers and key decision makers are struggling to find the useful business nuggets from this mountain of data.
As an example, take the typical offshore oil rig, which generates up to 2 terabytes of data per day. The majority of this data is time sensitive to both production and safety. Yet it can take up to 12 days to move a single day’s worth of data from its source at the network edge back to the data center or cloud. This means that analytics at the edge are critical to knowing what’s going on when it’s happening now, not almost 2 weeks later.
The case for analytics at the edge is not solely driven by bandwidth constraints. In many cases the data being analyzed simply has a useful life shorter than the time it takes to send the data to a central place for analysis. Location-based information is a perfect example. When someone (or something) is on the move, location-based information is only valid for a brief point in time.  Much of this data today is never analyzed at all because centralized analytics can’t provide insight quickly enough.
This scenario – repeated continuously in companies around the globe – has led to what I call “the Analytics Imperative” – the ability to extract meaning and outcomes in a world where 99.5% of the data collected is never analyzed.Infographic_AnalyticPNG2
Organizations need new strategies for analyzing these massive data sets. It is no longer viable to move 100% of your data to centralized data stores for analysis, as the examples above illustrate. Instead, customers today need solutions that enable real-time analysis to take place anywhere from the data lake or data warehouse to the edge of the network, including data in motion. The reality of IoE is that turning massive volumes of data into useful information will require analytics from the cloud to the data center to the very edge of the network.
Data and analytics will be the means by which value is extracted from the Internet of Everything. This explains why Cisco has entered the business of data and analytics in a big way with the introduction of Connected Analytics, pre-packaged analytics software ready for integration into existing Cisco infrastructures to enable powerful industry solutions. Why Cisco, you may be asking.
  • Connected infrastructure: Only Cisco has the connected infrastructure from the cloud to the data center to the edge to enable analytics everywhere
  • Agile pervasive data access: market-leading data virtualization capabilities  to leverage even the most distributed data
  • Real-time, streaming analytics at the edge: streaming analytic capabilities built right into our industrialized routers
  • The ability to leverage your existing infrastructure:Distributed analytics can be done either in NEW infrastructure or in EXISTING infrastructure. Using the intelligent Cisco infrastructure already in place dramatically reduces deployment and ongoing costs and significantly decreases time to deploy

  • Deep domain infrastructure expertise:  Nobody can understand network data better than Cisco; pairing that data with enterprise data can provide insights that aren’t possible without the network data, and THAT is where Cisco has created strength in our analytics.
  • Intercloud integration of private/public
  •  clouds:
  • Enables organizations to draw insights from data stored in both private and public cloud environments
  • Broad ecosystem of partners: 
  • Strategic partnerships have been critical to Cisco’s success over the past 30 years and continue to be so in the data and analytics space; from Hadoop partners to analytics partners, our customer solutions leverage a full stack of best-of-breed technologies from Cisco and our partners
Cisco approaches big data and analytics in a way no other company can, leveraging our strengths in hardware, software, services, and partnerships to embed powerful analytic capabilities from the data center to the cloud to the edge, providing insights across the most distributed and remote data.
The Analytics Imperative? We get it. And we are here to help you extract value from your data in ways no other vendor can. To learn more about Cisco Connected Analytics for the Internet of Everything, visit this site.

Friday, December 26, 2014

So you wanna be a data scientist? A guide to 2015's hottest profession 12-27

So you wanna be a data scientist? 


A guide to 2015's hottest profession


Are you good at math? Like, really good at math? Do you also know Python and, oh yeah, have deep knowledge of a particular industry?
On the off chance that you possess this agglomeration of skills, you might have what it takes to be a data scientist. If so, these are good times. LinkedIn just voted "statistical analysis and data mining" the top skill that got people hired in 2014.
Glassdoor reports that the average salary for a data scientist is $118,709 versus $64,537 for a programmer. A McKinsey study predicts that by 2018, the U.S. could face a shortage of 140,000 to 190,000 "people with deep analytic skills" as well as 1.5 million "managers and analysts with the know-how to use the analysis of big data to make effective decisions."
The field is so hot right now that Roy Lowrance, the managing director of New York University's new Center for Data Science program says he thinks it has peaked. "It's probably in a bubble," he says. "Anything that gets hot like this can only cool off." Still, NYU is looking to expand its data science program from 40 students to 60 over the next few years. The current school year won't be over for another five months and 50% to 75% of its students already have firm job offers.
Why the explosion? Linda Burtch, managing director of Burtch Works, a Chicago-based executive recruiting firm, notes that while tech firms like Google, Amazon, Netflix and Uber have data science groups, the use of such professions is now starting to filter down to non-tech companies like Neiman Marcus, Walmart, Clorox and Gap. "All these are companies looking to hire data scientists," she says.
The hope is that such professional will unearth new information that will prompt new streams or revenue or let a company streamline its business. Pratt & Whitney, the aerospace manufacturer, now can predict with 97% accuracy when an aircraft engine will need to have maintenance, conceivably helping it run its operations much more efficiently, says Anjul Bhambhri, VP of Big Data at IBM.
Though IBM just released its freemium, cloud-based Watson Analytics program this month, most often data scientists have to create homegrown software programs to analyze unstructured data, which is one reason that programming skills are required.

Schooling

Lowrance says there are basically three skills that a data scientist needs to possess: math/statistics, computer literacy and knowledge of a particular business domain (like autos, for example.) NYU's program teaches those so that each area of expertise builds on the other. When you graduate, you're sort of a jack-of-all-trades for data crunching. "When working on data science projects in coursework they have to do all the jobs," he says.
Not everyone has to go through a college course to become a data scientist, though. A company called Metis, for instance, started offering a 12-week data science boot camp in September. The program, in New York, costs $14,000 and admission is highly competitive. Metis Cofounder Jason Moss says that about half the students come in with a Master's or PhD.
Just a couple of weeks after the first boot camp ended in early December, Moss said six of the class's 15 students had job offers.
"I don't think it's a replacement for college," Moss says of his program. "I think college is about more than the fastest path to getting a job. I also don't believe that you have to have gone to college to be successful as a data scientist," he says. "There's a personality type - innately curious, has grit, wants to figure things out — that does well."
Anmol Rajpurohit, an independent data scientist and consultant, says being a fast learner is most important attribute for this line of work. "Generic programming skills are a lot more important than being the expert of any particular programming language," he says. "Living in an age of rapid technology advancement, we see languages quickly becoming obsolete and new languages quickly getting popular. Thus, a fast learner will go a lot farther than an expert."
Lowrance says that he believes boot camps and online-based courses can be helpful for candidates strong in some skills, but weak on others. One virtue of NYU's program is that it teaches the skills sequentially so that they build on each other. "We give you everything you need in an order that makes sense," he says.
What data scientists do?
"On an average day, I manage a series of dashboards that tell our company about our business — what the users are doing," says Jon Greenberg, a data scientist at Playstudios, a gaming firm. Greenberg is a manager now, so he's programming less than he used to, but he still does his fair share. Usually, he pulls data out of Apache Hadoop storage and runs it through Revolution R, an analytics platform and comes up with some kind of visualization. "It may be how one segment of the population is interacting with a new feature," he explains.
Greenberg got a Master's degree in statistics six years ago. He expected to go into government work, but was surprised to see that data scientists were so in demand in the private sector. "It was definitely not as hot a field then," he says. Now, he says he gets about one call or email a day from a headhunter. "It's not me," he says. "They probably bother everyone else [with this expertise]."
For Greenberg, employability is a plus, but he loves the work itself. "I think it starts with, you have to have an analytical mind. You have to be curious," he says. "You have to be flexible and creative and think of a different way to solve problems." The only downside of the job, Greenberg says, is the time spent "cleaning" data — pruning it to remove irrelevant findings. "That part's not that exciting and you spend a lot of time doing it," he says.
Rajpurohit says he spends a lot of his energy cleaning data, but also researching. "A significant part of my time is spent on research, because I often come across absolutely new problems and thus, have to study the latest literature on research in that particular field or reach out to experts on those topics for advice," he says.
"Despite its name, data science requires a good mix of both art and science. The science part is obvious –- mathematics, programming, etc. The art part is equally important –- creativity, deep contextual understanding, etc. Both the parts put together make one a great problem solver."
That said, Rajpurohit acknowledges that 'working in Data Science is not even remotely as sexy or glamorous as it is being perceived these days. This field is definitely gaining significance (and seeing high pay offers) across organization, but there is a lot of not-so-exciting tasks that a data scientist needs to work on almost daily basis."

Is this the career for you?

If the idea of spending much of your day programming and analyzing dashboards for relevant information appeals to you, then you might have the makings of a computer scientist. If you're merely motivated by the salaries, though, you may have a tougher time. Consider: People who fall into this line of work often spend their spare time writing programs and analyzing data just to amuse themselves.
Adam Flugel, data science recruiter for Burtch Works, recalls a recent candidate, a PhD holder, who he placed at Electronic Arts this fall. "What really stood out was the work that he was doing for fun in his free time," Flugel says. "He was involved in the online multiplayer game World of Tanks and led a “clan”, basically a team of players. He created a utility to scrape data from the game server and then ran analytics on that data to evaluate his clan’s performance. He used this info to figure out how to adjust their strategy, what types of players he should recruit to improve the team, etc."
If you don't love data for its own sake, then you will find it hard to compete with such candidates. Burtch, however, says everyone should learn to love data, if only for the sake of their career. "Within 10 years, if you're not a data geek, you can forget about being in the C-suite," Burtch says.
But what about Steve Jobs, Bill Gates and other such visionaries who saw the big picture and didn't get bogged down in the minutiae of data science? "That was 30 years ago," says Burtch. "I'm talking about the next 10 years."

Tuesday, December 23, 2014

What is sentiment? 12-24

What is sentiment?


Sentiment is the tone of voice in which a particular document was written. 

We as humans have usually have no problems determining the sentiment of documents. As we read a text we just know whether it's positive or negative. We've learned that certain words are indicative of a positive sentiment. These are for example words such as good, grand or hero. Other words like terrible, bad or violent are clearly indicative of a negative sentiment. And even when it comes to sarcasm like "go read the great book" we know this is negative for the movie that was reviewed. How different is this for computers that take everything literally.

However, we as humans are limited in that we cannot read and score that many documents in a day. 

It's difficult to get to the big picture really fast. For this we need computers.

How do software programs such as BuzzTalk determine sentiment?

Teams of linguists have created lists of words that correspond with a certain sentiment. 

Each word has a 'force' since for example 'great' is more positive than 'good'. Phrases that match the list are scored with a number between -9 and +9. When the program has reached the end of the document and tagged all the relevant words you can calculate the average score. This average score corresponds to the tone of the document.
Now, this is not all that BuzzTalk does in relation to sentiments but we'll come back to that at a later moment.

How can companies use automated sentiment analysis?

Suppose you've started a big marketing campaign to increase your brand awareness. 

You can use sentiment analysis to determine the public's response to your brand. Are they talking about you? Is their response positive or negative and if negative... how negative and why.

You need to know this kind of information so you can adjust your campaign. 

Also you want to know whether these were marketing dollars well spent.

Since BuzzTalk uses effective sentiment tagging you can easily analyze large amounts of publications on the web. 

We as humans can spot patterns and trends, which would not be possible when we read and analyze only a small portion of the web.

Thursday, December 11, 2014

Building a private cloud, of sorts, with OwnCloud 12-12


Building a private cloud, of sorts, with Own Cloud


Getting cloudy has always been a mixed proposition in the IT world. Your users want the convenience of using a variety of devices and having their work accessible on all of those devices from wherever they are, whereas you still have to worry about data security, lost computers, federal regulation and the control that is necessary to ensure your organization's information technology resiliency. Add the fact that most cloud services like OneDrive, Google Drive or Dropbox -- let's face it, the ones that your users want -- are consumer-oriented services that lack the ability to be managed and controlled centrally, and you have a face-off for the ages.

OwnCloud purports to solve these problems with the notion of a private cloud, but not in the sense that a private cloud is simply a data center you own and control that has elements of automation including self-service delivery, redundancy and easy spin-ups and spin-downs of various offerings and services. Rather, OwnCloud is more like a Dropbox that is not under Dropbox's control or a Google Drive where Google is not reading all of the data; it is a service you, as either the administrator for a larger organization or you as the end user, control, where you can decide which items you want shared with others, which devices you can access that data on and what apps you want to access that data.

For the free community edition that operates under open-source licensing rules, you have two choices: Host the code yourself on hardware that you own, all the while retaining complete control over the files and folders you manage with the service, or find a hosting partner that will run the OwnCloud platform for you, with the implication that you then must store at least some of your data at that partner. 

OwnCloud makes available a list of these providers. All have different methods of pricing what they offer, how much storage comes with their various plans and so forth. The OwnCloud project does not appear to endorse or have an emphasized partnership with any of these providers.

In this piece, I want to dig into the technical details of the OwnCloud offering and highlight some of its plusses and minuses. Let's take a look.

OwnCloud security  Arguably the strongest reason for adopting your own off-device storage and synchronization program is the ability to secure the contents of your users' files and folders.

OwnCloud relies on encryption to do most of the heavy lifting to protect the data under its control. OwnCloud uses Transport Layer Security (TLS) to protect data as it is in transit from device to server and vice versa, and then a separate encryption app to encrypt and decrypt the data. The encryption app uses a long, random key protected by the password for each user's account to encrypt user data.However, the decryption and encryption always take place on the server, leaving you as the administrator with control over what is stored within your OwnCloud deployment since you can control the encryption on the server. Also, if encryption were performed on each user device, the server would not have the key available to decrypt files and allow a Web interface to function.

What is especially interesting about the OwnCloud encryption app is that it can work with Dropbox, Google Docs, external servers accessed through the  WebDav HTTP protocol extension and more. This adds a layer of security to these other services and lets you informally extend the amount of storage that is available to you and your users while still providing a measure of protection during their use.

With memorable Dropbox security failures like the "everyone can read all of everyone else's data" incident of a few years ago and recent password integrity issues, this can be comforting to all manner of users. The main feature OwnCloud provides here is its seamless encryption.

The free community edition also includes support for integrating identities with LDAP directories and in particular Active Directory, so users can take advantage of their existing user accounts when using the service.

Synchronization and collaboration featuresPerhaps the most useful user-oriented feature of OwnCloud is the ability to synchronize data stored under the software's purview to a tablet, a phone or a central server through the use of a Web interface and the user's laptop or desktop computer. OwnCloud comes with clients for both the iOS and Android platforms (there is no Windows Phone support), although you have to pay extra for those unless you are using the paid enterprise edition of OwnCloud, in which case the mobile clients come included in your subscription.

In addition, in the community edition, users can edit their documents through a Web interface and they also get a nice photo gallery and photo-sharing capability. There is also calendar support, though for any shop on Microsoft Exchange or other groupware, it is difficult to see how the OwnCloud calendar really adds much value on top of that existing investment.


As far as collaboration goes, you can share files with users of other OwnCloud installations, and you can also set up alerts so that your users know when others have accessed the files that they have shared. It also includes support for versioning, so in case of a mistake, users can roll back files they have changed to earlier versions.

Installing Own Cloud

You can research a lot about setting up the OwnCloud service, but it is best to just accept one fact from the beginning: OwnCloud really prefers installing itself on Linux distributions, primarily because it relies on both PHP and MySQL for its core functioning, and neither is really built for running well and trouble-free on the Windows Server platform.

Installing on Linux

To install on Ubuntu Linux or its variants, you can get all of the prerequisites in place by entering the following three commands in the shell:

apt-get install apache2 mysql-server libapache2-mod-php5
apt-get install php5-gd php5-json php5-mysql php5-curl
apt-get install php5-intl php5-mcrypt php5-imagick

Next, from the installation page, click the blue "Archive File for server owners" button in the "Install OwnCloud Server" section, and then click Download Unix to download the package to your server system. You will get a file with a .tar.bz extension, which represents the core module of OwnCloud.
Now, just pop out the archive file with the following command:

tar -xjf owncloud-x.y.z.tar.bz2

Next, copy these files to the document root directory of your Web server. For Apache on Ubuntu, this is usually the /var/www directory. Here is a command that will do the heavy lifting:

cp -r owncloud /path/to/webserver/document-root

Make sure the Web user account on your system owns the Owncloud directory. On Ubuntu systems, this is the www-data user. On other Linux systems, this might be the apache account or the webuser account.

Your PHP configuration file will tell you the right user account for your system. The chown command shown below will assign the right ownership to these subdirectories:

chown -R www-data:www-data /var/www/owncloud

Now, enable SSL in Apache. On Ubuntu, again four simple commands will take care of this for you, even when using the default self-signed certificate you get in the base Apache package:

a2enmod ssl
a2ensite default-ssl
service apache2 reload
a2enmod rewrite

Then you can run the installation wizard by navigating to https://servername/owncloud. Since you are using a self-signed certificate, you might have to accept whatever warning your Web browser throws up. Then simply follow the wizard.

For more detailed information on installing OwnCloud on a variety of Linux distribution variants, visit the OwnCloud online documentation
.
Installing on Windows Server 2008 or higher

The set up on Windows looks different. Here's the process in a nutshell.
  1. From the Start menu, choose Control Panel, Programs and, then under Programs and Features, Turn Windows Features On and Off.
  2. Server Manager appears. Click Roles, then click Add Roles, and then add the Web server role. Make sure CGI support is enabled, FTP support is disabled and WebDAV publishing is disabled. (OwnCloud needs to own WebDAV at the application level, so disabling Windows WebDAV here will prevent conflicts.)
  3. When the Add Roles Wizard is finished, reboot your server and then install PHP by going to the PHP for Windows download page and grabbing the PHP 5.3 “VC9 Non Thread Safe” version installer (near the bottom of the page) in either 32-bit or 64-bit editions.
  4. Once the download finishes, run the installer, read the license agreement, agree, select an install directory and select IIS FastCGI as the install server.
  5. Choose the defaults in the remainder of the wizard and then finish it out.
  6. Next up, we need to install MySQL, so head over to http://dev.mysql.com/downloads/ . then download the MySQL Community Server edition and run the installer in the Typical Installation configuration.
  7. Once the installation completes, choose to launch the MySQL Instance Configuration Wizard, choose a standard configuration, click to install MySQL as a Windows service and enable the Launch the MySQL Server Automatically button.
  8. Configure a user account on the next page and then click Execute and Finish once the wizard is done trundling.
  9. Next, install OwnCloud itself by downloading the blue “Archive File for server owners” package from http://owncloud.org/download. Unzip the .tar.bz file by using WinRAR or some other utility that supports the format, since Windows does not natively know how to read it, then copy the files to C:\inetpub\wwwroot, the Windows Website default directory.
  10. Then simply follow the installation wizard, as explained in the next section.
  11. The installation wizard
Even after tediously getting the OwnCloud code on your system, you are still not done. You now have to correctly set up the environment. The wizard, however, makes this a little easier than the initial setup steps.

Create an administrator account, including a username and password.

Under advanced options, you can choose a different data directory on the server storage for the service, and also you can set up either SQLite or MySQL for the service's database needs. Note you will need to install SQLite if you want to use it prior to launching the installation wizard.
Then click Finish Setup, and OwnCloud will set up its environment.

An analysis

For shops with a lot of Linux expertise, OwnCloud makes a lot of sense. It was built to live on those platforms. It uses PHP and MySQL extensively. As an open-source product, it relies a lot on community support and expertise to handle feature requests and issues.

For smaller shops without much built-in IT knowledge, you can run OwnCloud on most Web hosting platforms that run a few bucks a month, so it could be a good way to get a ton of functionality for a very low price, with some security built in, too. OwnCloud is a great fit for tiny businesses with hosting plans and large businesses with the necessary expertise to run OwnCloud servers in a good security posture.

For Windows organizations, however, it becomes a much murkier picture. Using a package that was built for Linux on Windows is always a daunting task. PHP and MySQL on Windows probably do not get enough testing (as compared to native Windows apps); you would have to do a lot to convince me otherwise. Patching and updating for both new features and security holes are much tougher propositions; you generally need a third-party engine to perform this sort of maintenance, since Windows Server Update Services generally ignores PHP and MySQL.

There is a paid support offering for businesses in OwnCloud Enterprise, which aims to solve many of these shortcomings. It also supports authentication integration using SAML -- a common standard -- and provides logging and backup systems and support for Microsoft SQL Server. There's also a product that allows admins to connect OwnCloud to Windows network drives, and manage and secure files in that way. The software supports network drives hosted on Windows Server 2008, 2012, Windows 7 or 8, as well as Linux-based Samba (emulating Windows). But this setup requires the paid Enterprise edition of OwnCloud running on a Linux server.

For Windows shops, I would not recommend the community edition of OwnCloud and would head either to the enterprise edition -- which involves paying some money, and paying even more for 24 x 7 support -- or go to another service entirely.